All Models

Image Blending with Multiple Methods
Image Blending with Multiple Methods is a task that involves combining two or more images seamlessly to create a composite image using a variety of blending techniques. By leveraging multiple blending methods, such as alpha blending, gradient blending, or Laplacian pyramid blending, this task enables the merging of images while preserving the visual coherence and integrity of the final composition.
by @AIOZAI

Video to Canny Edge
Video to Canny Edge is the process of converting a video into a Canny edge representation, where edges in the video are emphasized and separated. Canny Edge is a popular algorithm in image processing and is often used to detect edges in images and videos.
by @AIOZAI
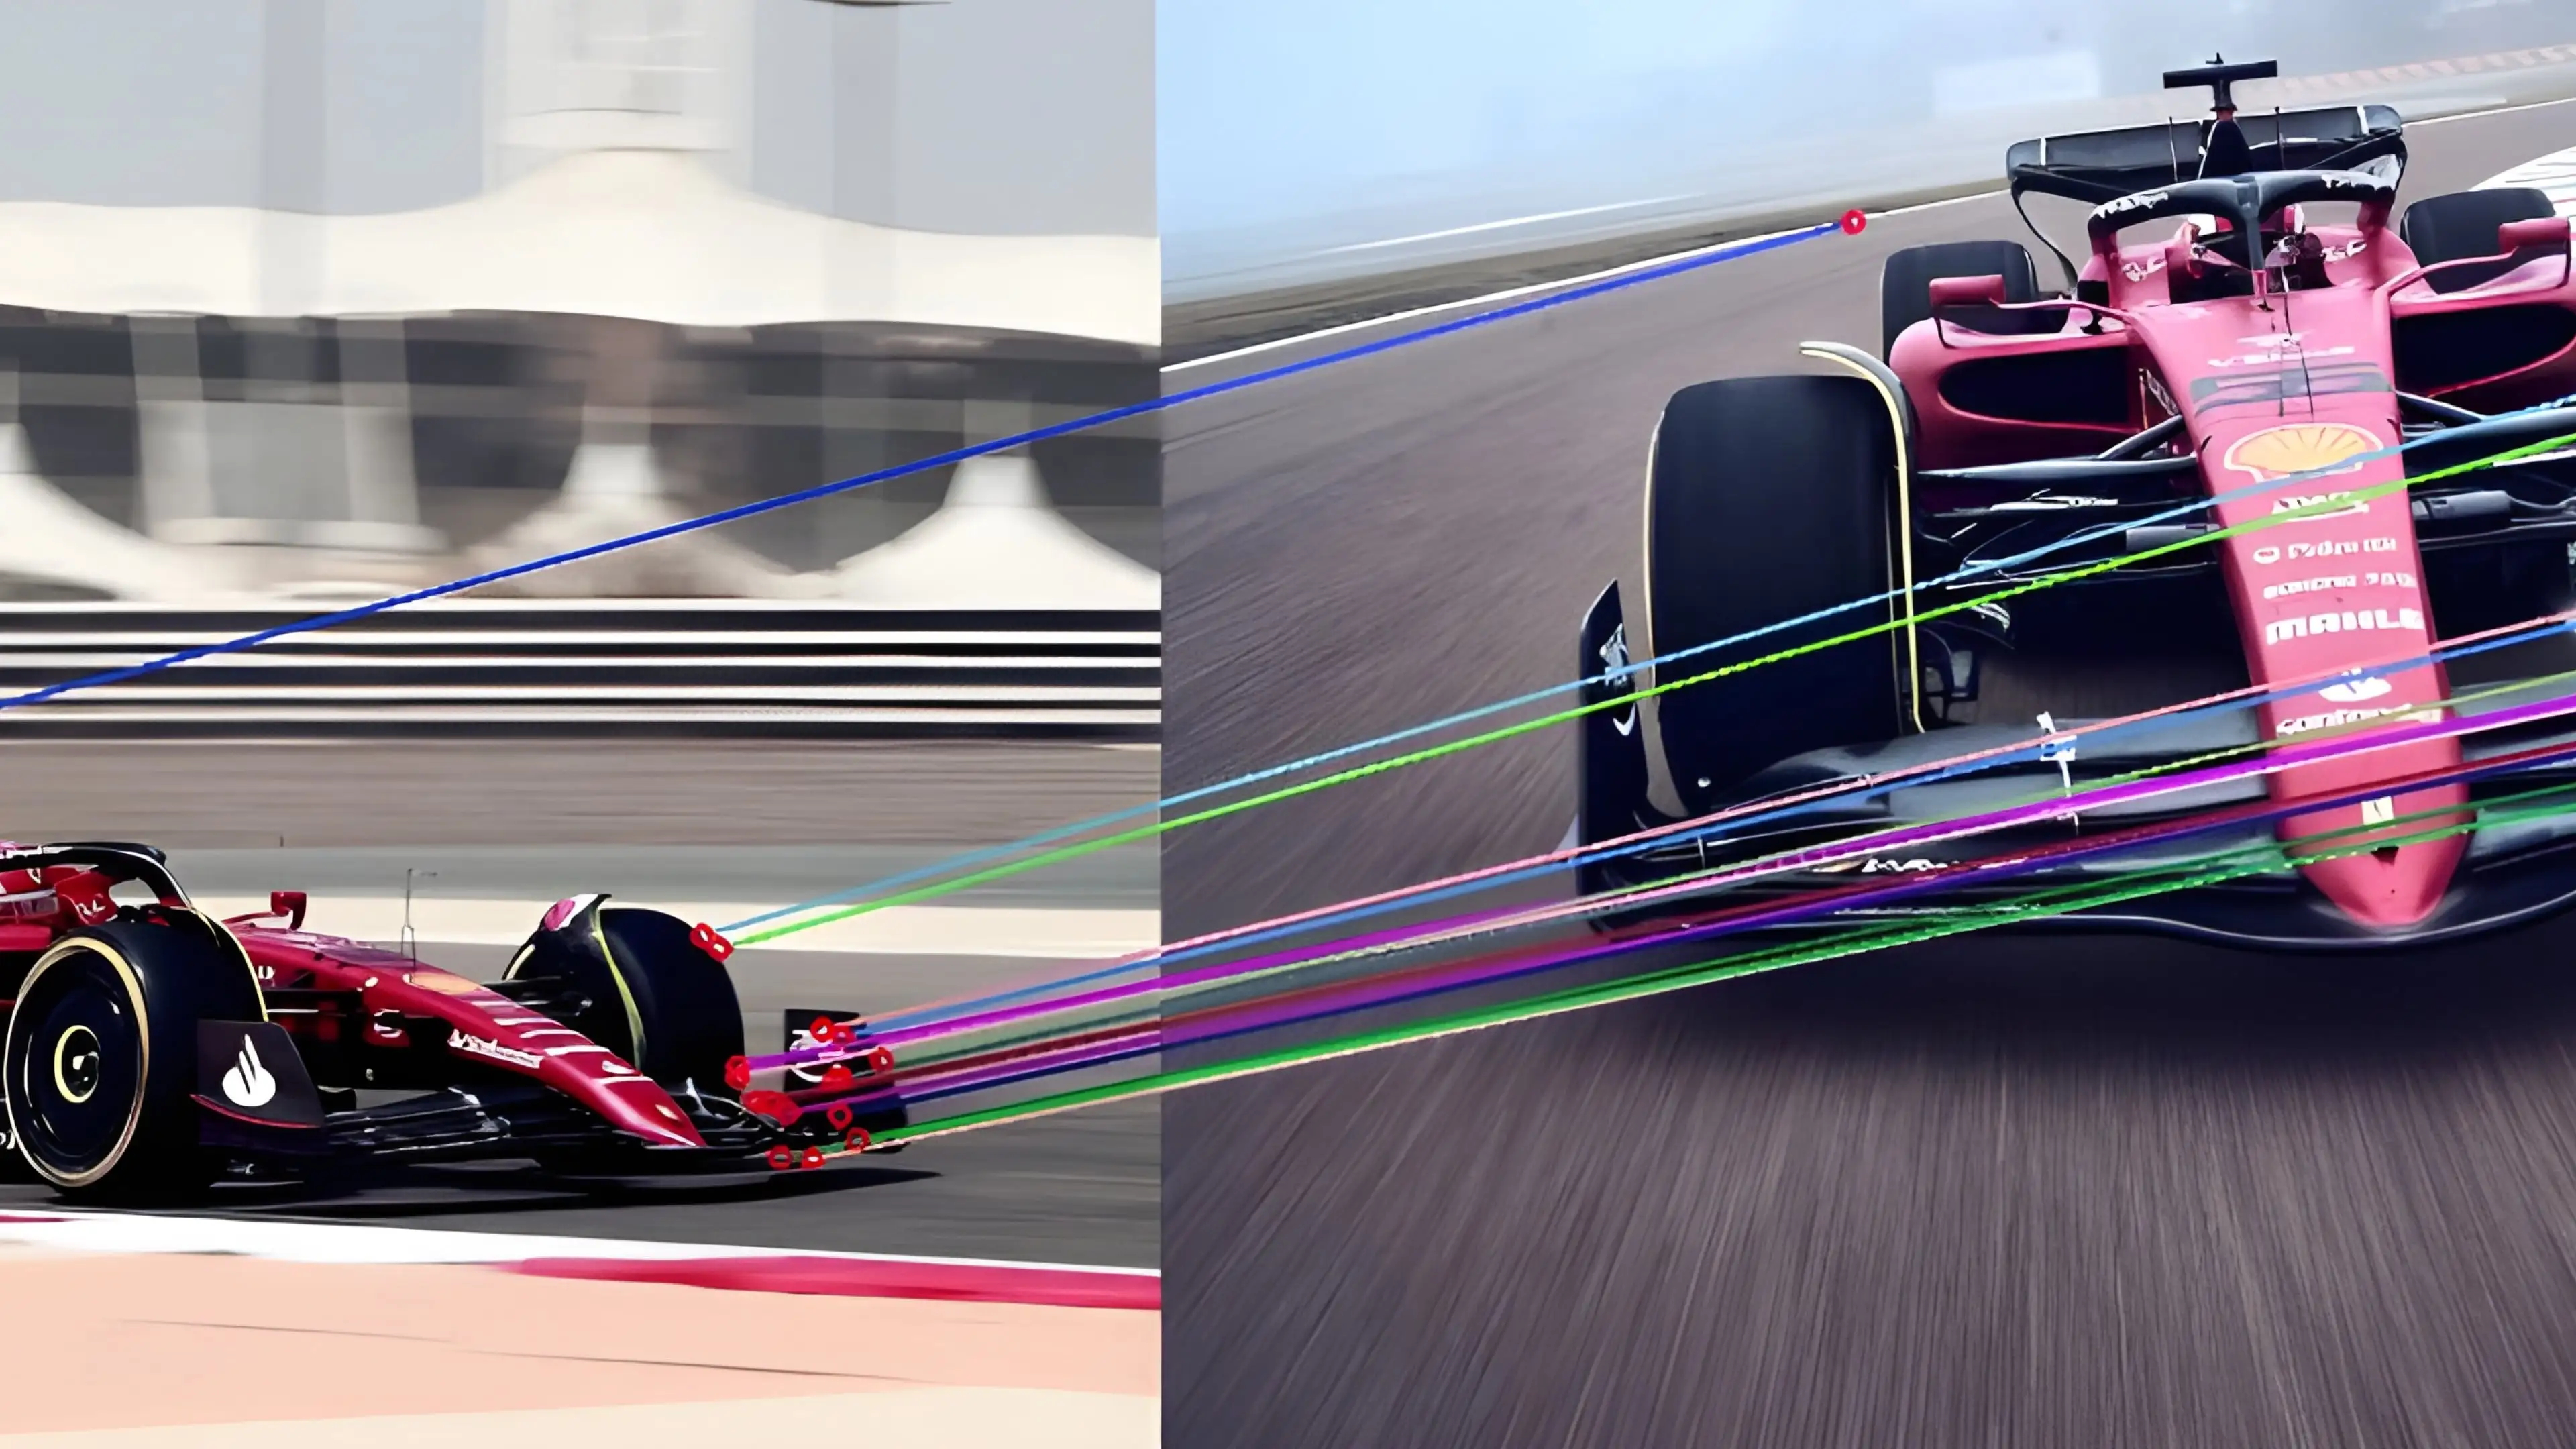
XFeat: Accelerated Features for Lightweight Image Matching
This is a task focused on enhancing the efficiency of image matching by leveraging lightweight yet highly discriminative features. XFeat employs optimized feature extraction techniques to identify key points and patterns in images, making it suitable for fast and accurate image comparison.
by @AIOZAI
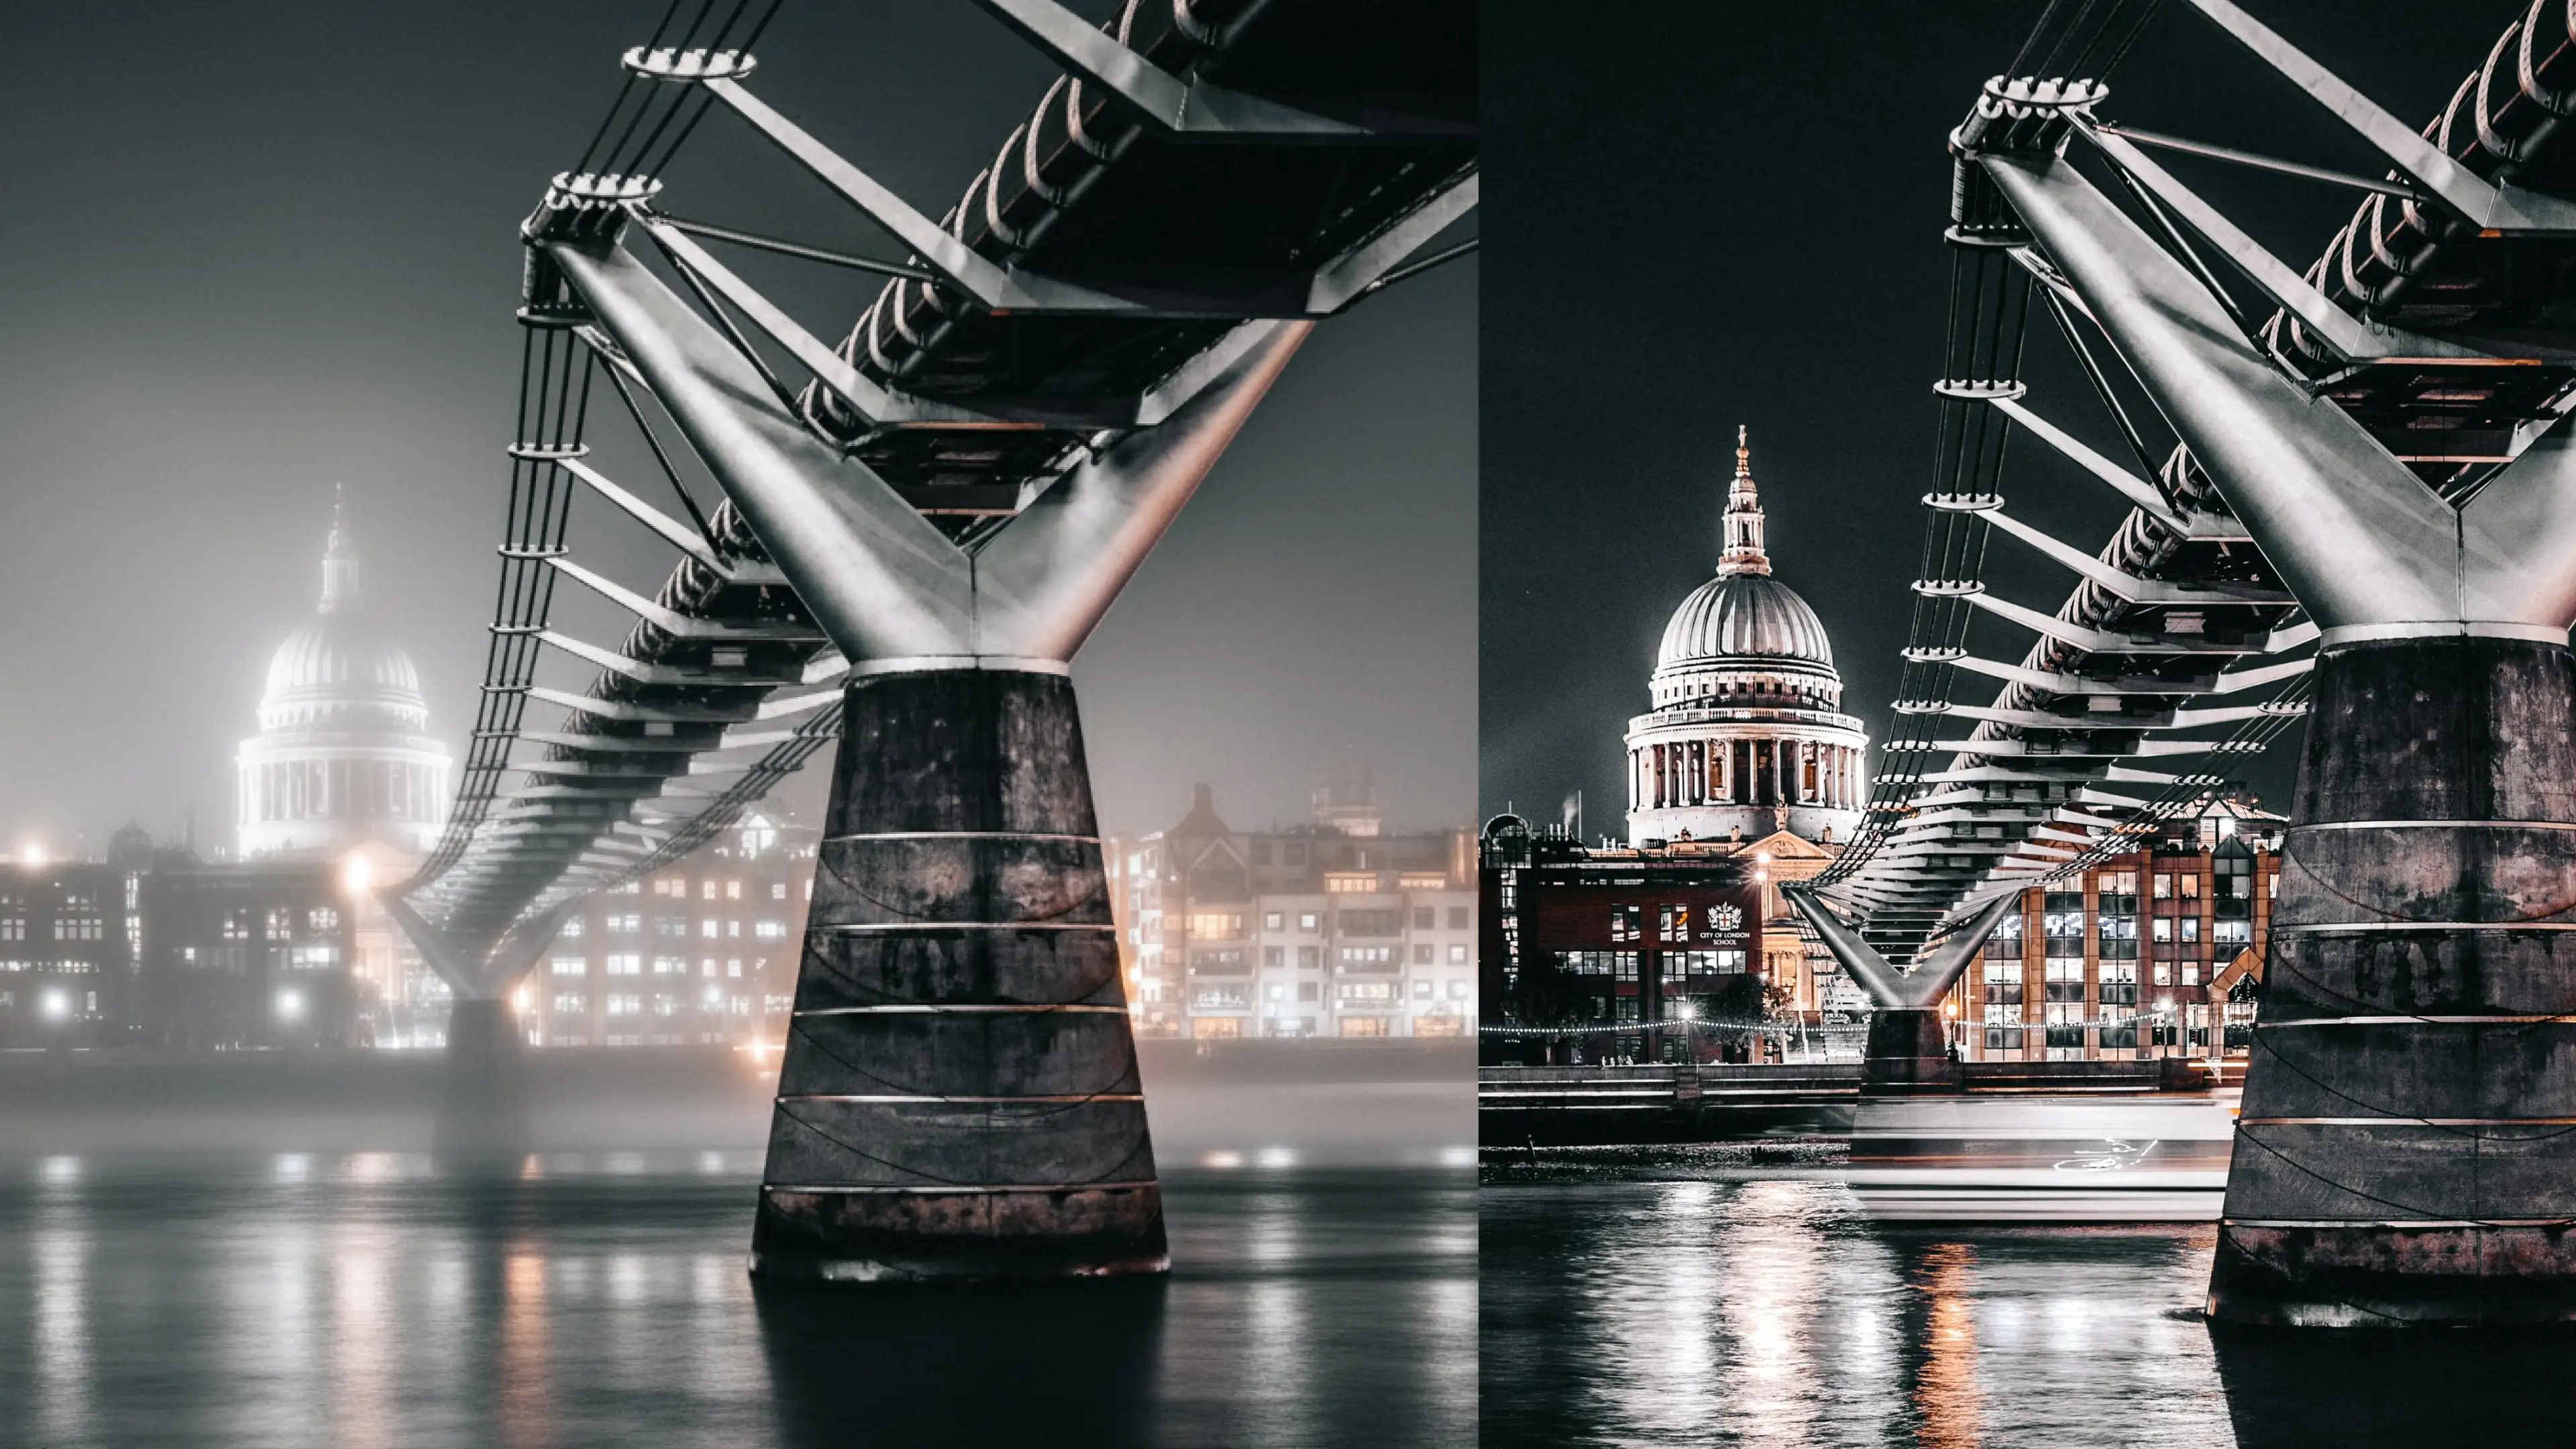
DehazeFormer
DehazeFormer is a deep learning model designed for single image haze removal. Leveraging a transformer-based architecture, it effectively restores image clarity and contrast by removing haze, making it suitable for applications in autonomous driving, remote sensing, and image enhancement.
by @AIOZAI
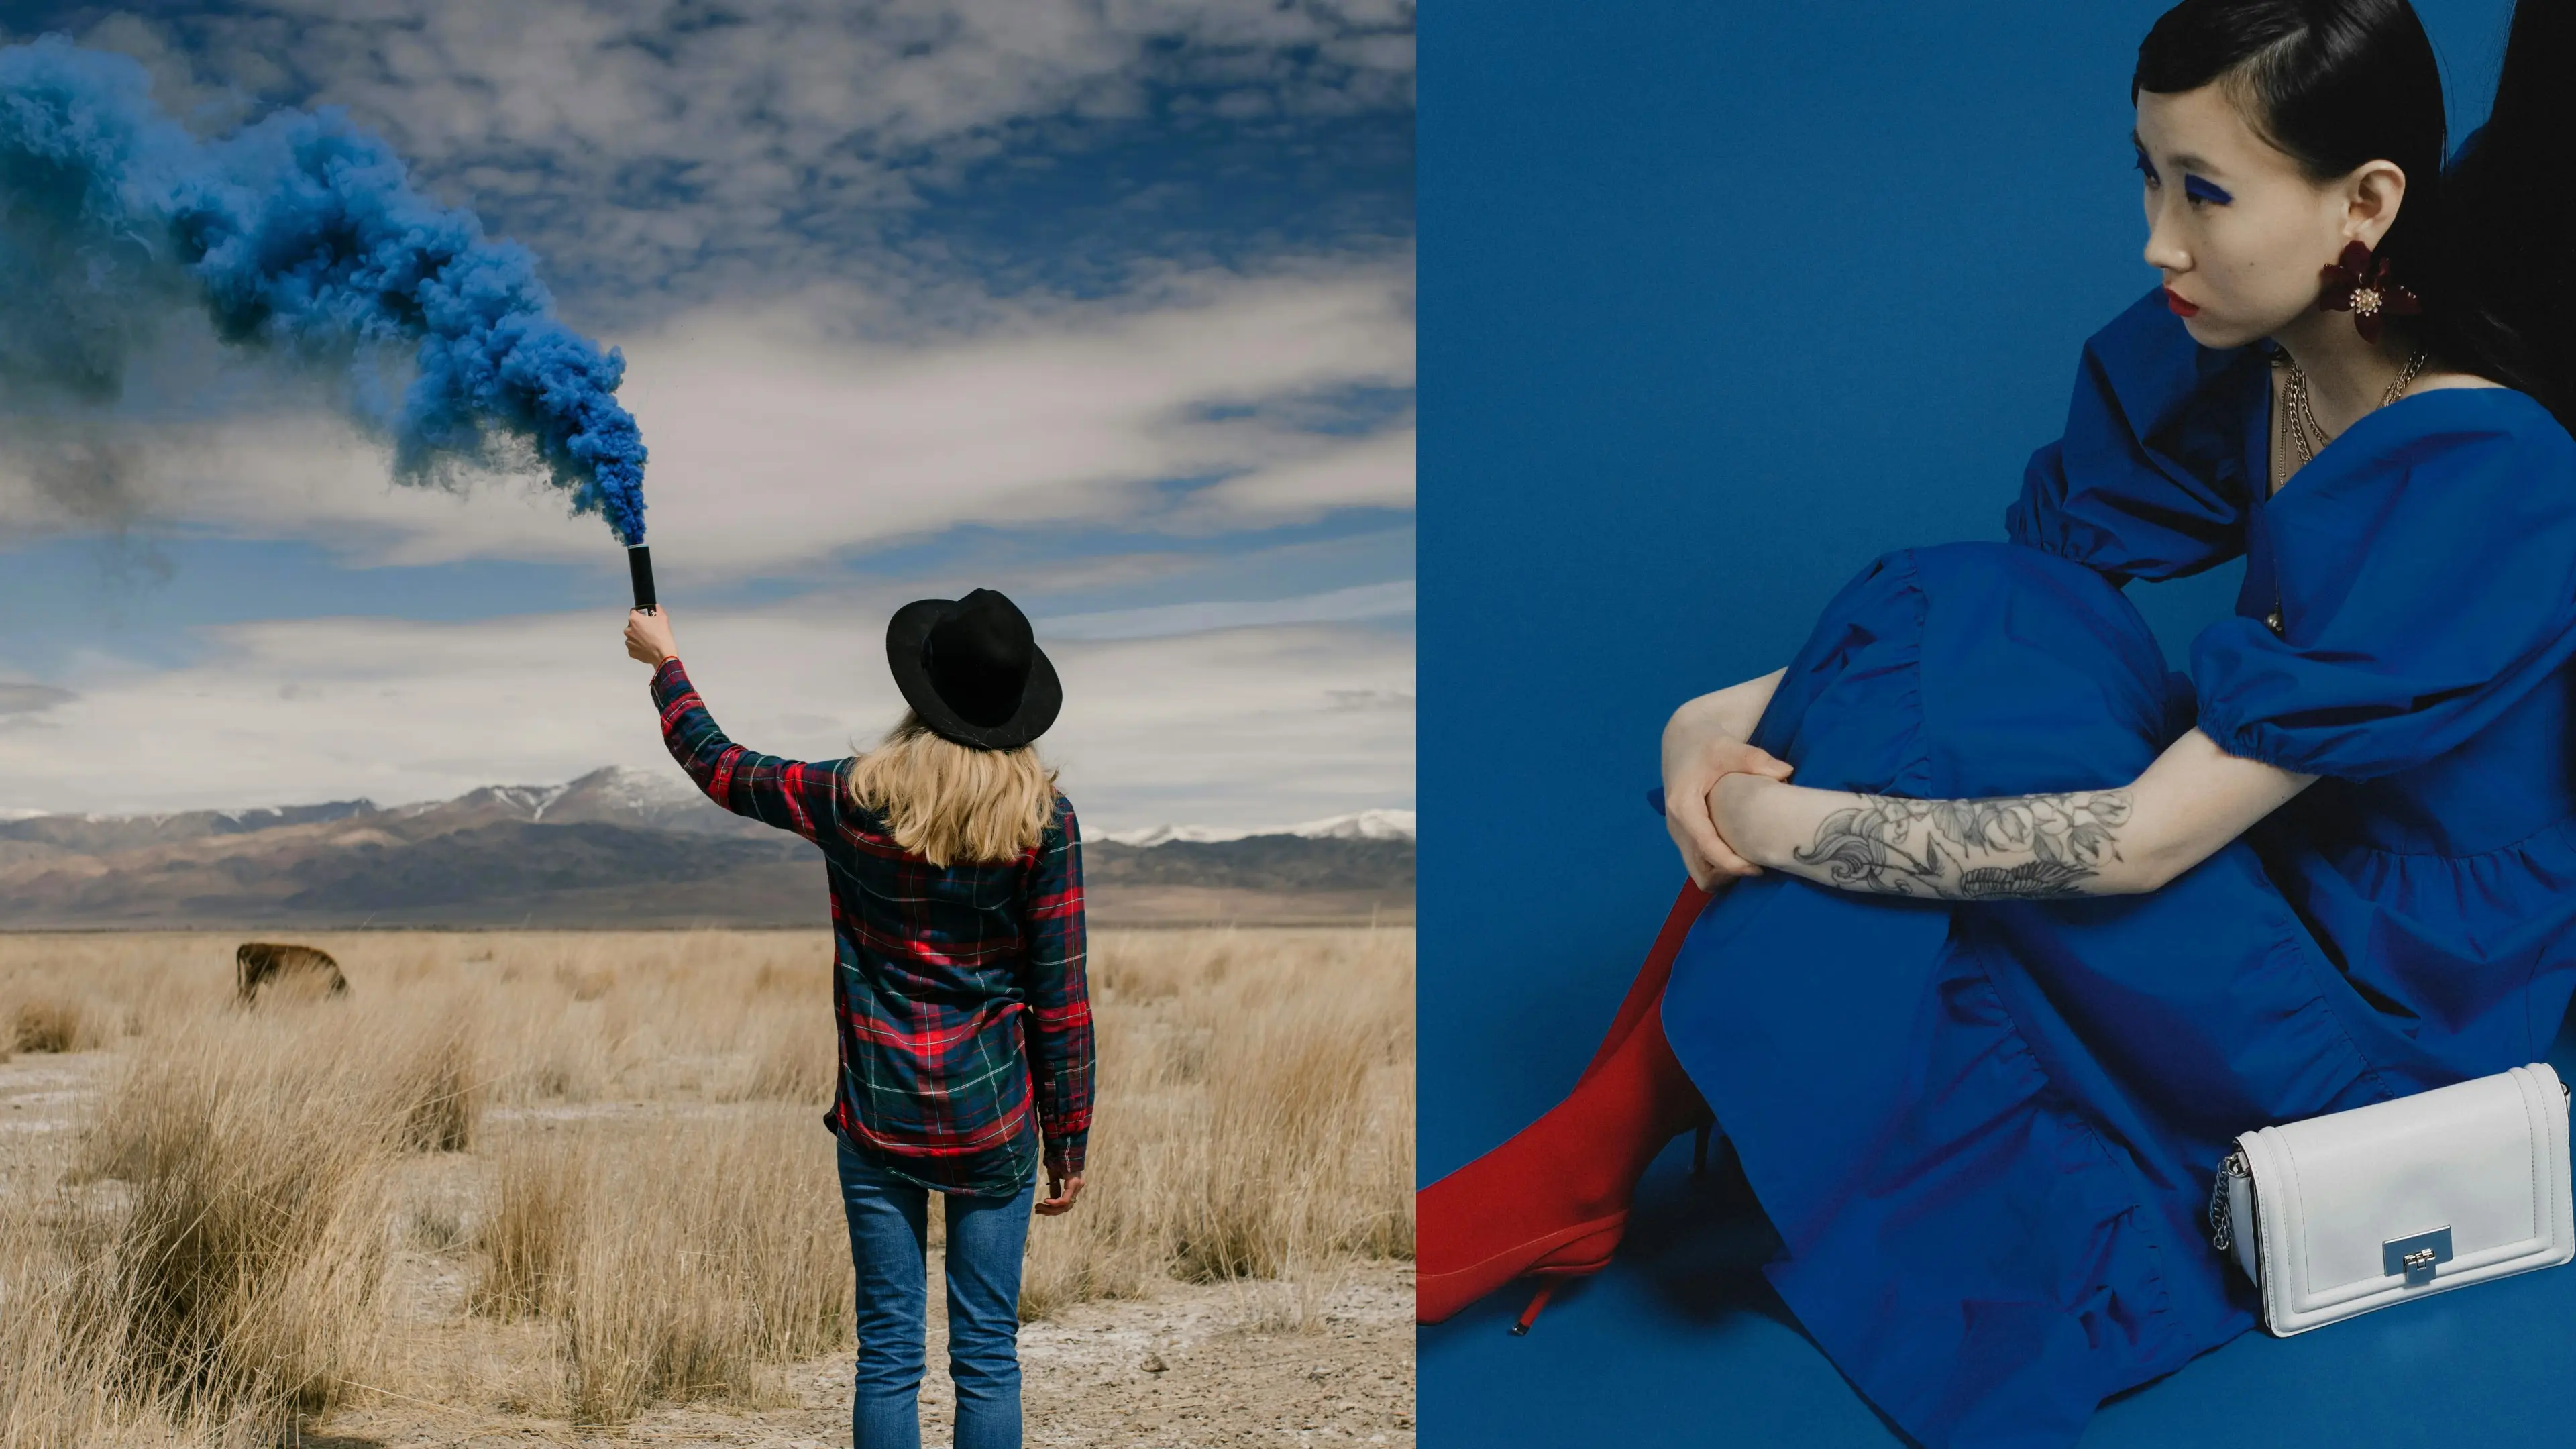
Color Harmonization
Color Harmonization is a computational model designed to adjust and enhance the color balance of an image based on harmony templates, as proposed in the paper by Daniel Cohen-Or et al. The model improves visual aesthetics by aligning image colors with established color harmony principles. It supports multiple harmony templates and can be integrated with user interfaces for visual quality assessment using metrics from interfacemetrics.aalto.fi.
by @AIOZAI

Background Replacement
Background Replacement is a powerful tool that enables users to easily change the background of their images, opening up endless possibilities for creative transformations, and visual enhancements.
by @AIOZAI

Image Super-Resolution with SeemoRe
Image Super-Resolution with SeemoRe is a task aimed at improving the process of image super-resolution by leveraging expertise in the field. This task involves incorporating techniques that identify and utilize expert knowledge or specialized information to enhance the efficiency and accuracy of image upscaling.
by @AIOZAI
Color Extraction
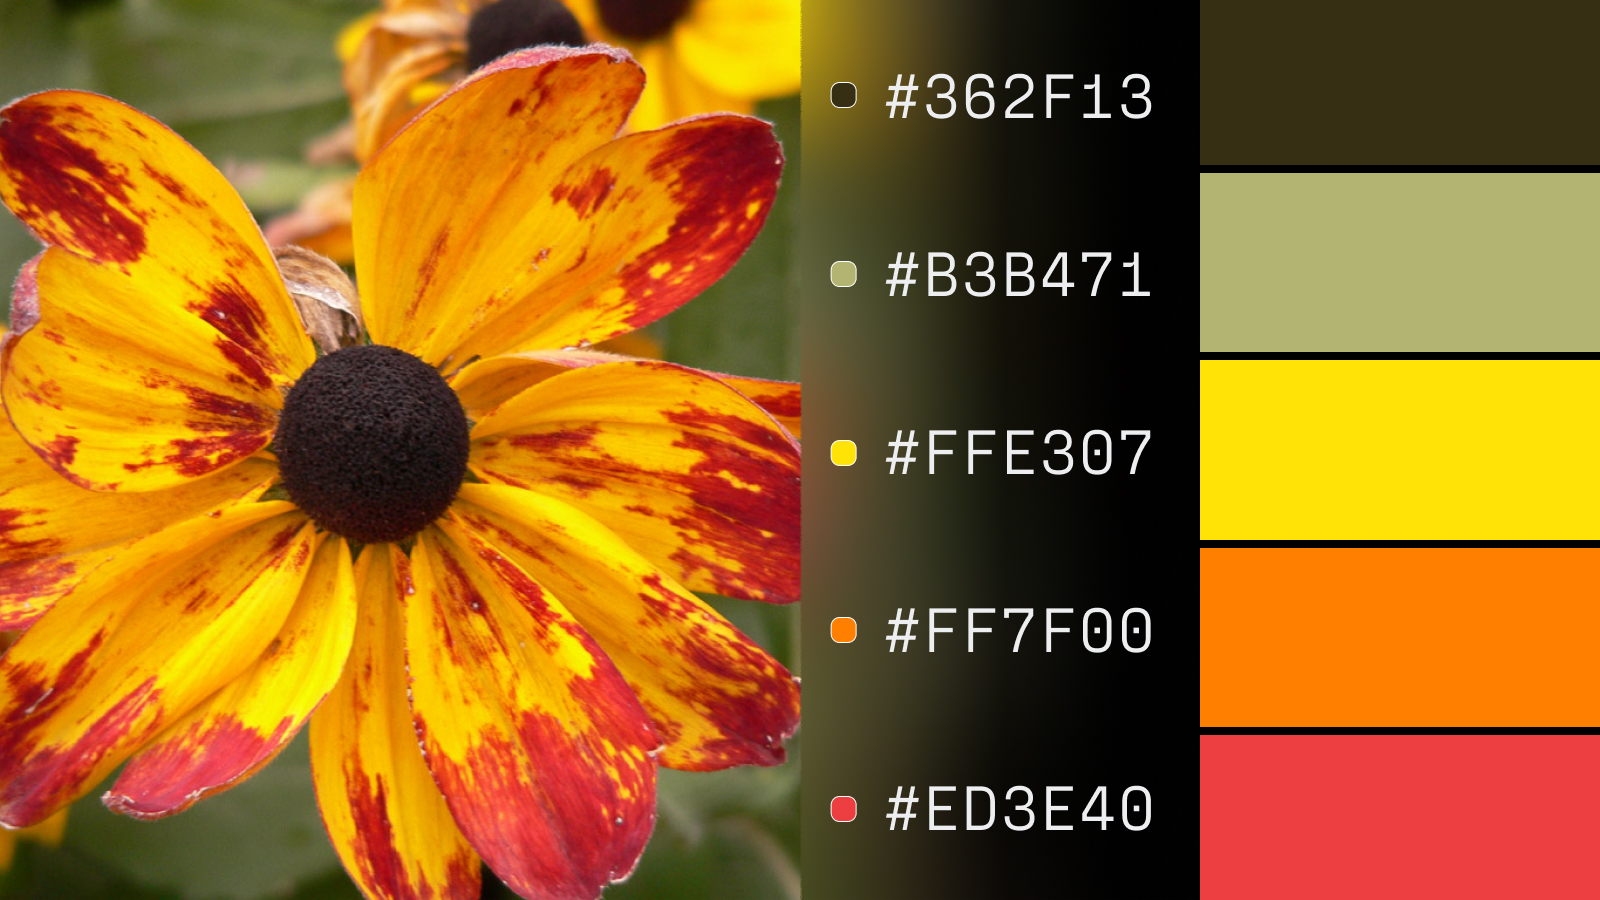
Color Extraction is a task in computer vision that involves the extraction and analysis of colors from images or videos. The objective of this task is to identify and isolate specific colors, or color ranges present in the visual data.
by @AIOZAI
Text Generation by LiteLlama
We present an open-source reproduction of Meta AI's LLaMa 2. However, with significantly reduced model sizes, LiteLlama-460M-1T has 460M parameters trained with 1T tokens.
by @AIOZAI

Archer Image Generator
Archer Image Generator user Archer Diffusion, is a highly specialized Image generation AI Model of type Safetensors / Checkpoint AI Model created by AI community user civitai. Derived from the powerful Stable Diffusion (SD 1.5) model, Archer Diffusion has undergone an extensive fine-tuning process, leveraging the power of a dataset consisting of images generated by other AI models or user-contributed data. This fine-tuning process ensures that Archer Diffusion is capable of generating images that are highly relevant to the specific use-cases it was designed for, such as landscapes, nitrosocke, archer.
by @AIOZAI

Cartoonize Image Diffusion
Motivation behind this pipeline partly comes from FLAN and partly comes from InstructPix2Pix. The main idea is to first create an instruction prompted dataset (as described in our blog) and then conduct InstructPix2Pix style training. The end objective is to make Stable Diffusion better at following specific instructions that entail image transformation related operations.
by @AIOZAI

Housing Prices Challenge
Model for Housing Prices Challenge
by @AIOZAI

Movie Reviews Challenge
Model for Movie Reviews Challenge
by @AIOZAI

Pothole Detection Challenge
Model for Pothole Detection Challenge
by @AIOZAI

Semantic-Guided Low-Light Image Enhancement
Semantic-Guided Low-Light Image Enhancement is a task that integrates semantic information into the process of enhancing the quality of images captured in low-light conditions. By incorporating semantic guidance, this task aims to improve the accuracy and effectiveness of enhancing low-light images by considering the context and content of the scene.
by @AIOZAI

Image to Anime
The goal of Image to Anime was to create a new version of the image that would possess the same clean lines and evoke the characteristic feel found in anime productions, capturing the unique artistry, and aesthetics associated with this style.
by @AIOZAI