All Models
Monocular Depth Estimation
Generate a single-channel depth-map visualization from one RGB image with a DPT model backed by DINOv2 Base and trained for the KITTI domain
by @AIOZAI
Architectural Instance Segmentation
Segment architectural elements in a building image with a custom YOLOv8n segmentation checkpoint packaged for the AIOZ AI Node runtime.
by @AIOZAI
Face Anti-Spoofing Challenge
Model for Face Anti-Spoofing Challenge
by @AIOZAI
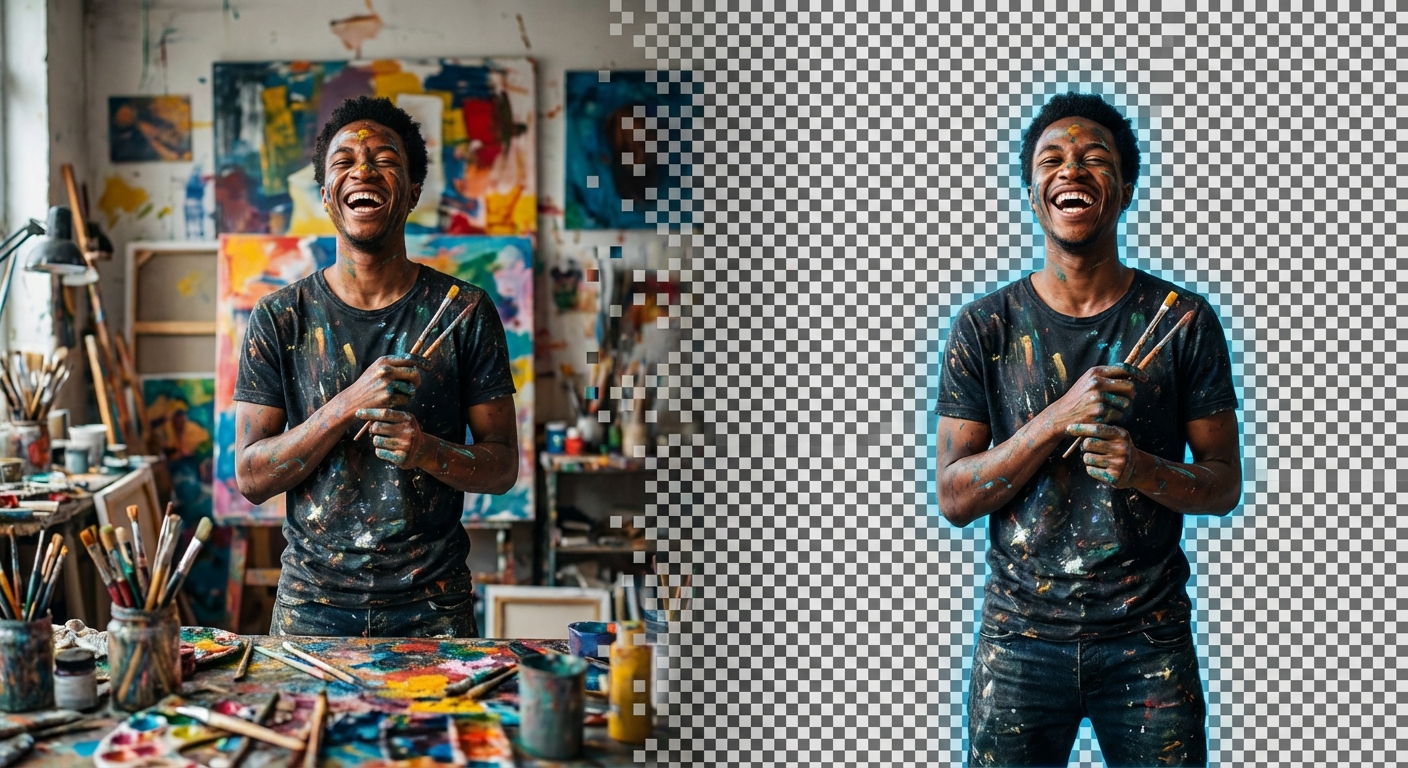
Background Removal
Background Removal is an image processing technique, used to separate the main object from the background of a photo. Removing the background helps highlight the product, subject, or character, bringing a professional and aesthetically pleasing look to the image.
by @AIOZAI
DWPose: Whole-Body Pose Estimation
DWPose is a whole-body pose estimation model that detects human keypoints across the body, face, and hands. It provides ONNX weights for efficient inference and is commonly used in human pose analysis and virtual try-on applications.
by @AIOZAI
Road Accident Risk Prediction Challenge
Baseline source code for Road Accident Risk Prediction Challenge
by @AIOZAI
Speech Emotion Recognition with Wav2Vec2
Speech Emotion Recognition with Wav2Vec2
by @AIOZAI
TinyNet-A Image Classification
Classify images into 1,000 ImageNet categories with the compact TinyNet-A convolutional neural network.
by @AIOZAI
InsectSAM: Insect Segmentation and Monitoring
InsectSAM is a fine-tuned version of Meta AI's segment-anything model, optimized for insect segmentation and monitoring in the Netherlands. Designed for use with the DIOPSIS camera systems, algorithms and datasets, it enhances the accuracy of insect biodiversity segmentation from complex backgrounds.
by @AIOZAI
Qwen2.5-72B-Instruct
Qwen2.5-72B-Instruct is a flagship 72.7-billion parameter, open-weight model engineered for high-stakes AI production, advanced reasoning, and complex conversational tasks. Optimised with an 80-layer architecture using Grouped Query Attention (GQA), it delivers exceptional performance in coding, mathematics, and structured data tasks like JSON and table processing.
by @AIOZAI
Qwen3-0.6B
Qwen3-0.6B is a compact 0.6B-parameter causal language model from Alibaba Cloud’s Qwen team. Featuring a hybrid Thinking/Non-Thinking mode, it balances deep reasoning with fast, efficient responses. With support for a 32K token context window, over 100 languages, and native tool-calling via the Qwen-Agent framework, it is well-suited for lightweight chatbots, math/code reasoning, and agentic applications.
by @AIOZAI

Handwritten Digit Recognition Challenge
Baseline source code for Handwritten Digit Recognition Challenge
by @AIOZAI
Ministral-3 3B-Base 2512
Ministral 3 3B Base 2512 is a compact multimodal foundation model from Mistral AI. It combines a 3.4B-parameter language decoder with a 0.4B frozen vision encoder for native image understanding. Distilled from the 24B Mistral Small 3.1 through an iterative “Cascade Distillation” process, it preserves much of its teacher model’s capability while supporting a 256K token context window via YaRN RoPE scaling.
by @AIOZAI
MiMo-7B-Base
A 7B-parameter decoder-only language model developed by Xiaomi. Trained from scratch for mathematical and coding reasoning, it serves as the foundational checkpoint of the MiMo-7B series, providing a strong base for fine-tuning and reinforcement learning.
by @AIOZAI
Granite-4.0-Micro
A 3B-parameter long-context instruct model from IBM, finetuned for enhanced instruction following and tool-calling. Supports 12 languages including English, Chinese, Arabic, and Japanese. Built on a dense Transformer with GQA, RoPE, SwiGLU, and 128K context length. Trained using SFT, RL alignment, and model merging techniques for enterprise applications.
by @AIOZAI
Qwen-Image 2512
Qwen-Image-2512 is a 20B-parameter text-to-image generation model built on the Multimodal Diffusion Transformer (MMDiT) architecture with a frozen Qwen2.5-VL semantic encoder. It delivers photorealistic image generation, with improved human rendering, natural textures, and accurate text rendering in both English and Chinese for posters, infographics, and slides.
by @AIOZAI
Wine Quality Classification Challenge
Baseline source code for Wine Quality Classification Challenge
by @AIOZAI
Wan2.2-Animate-14B
A character animation and replacement video model: give it one character image and a driving video, and it transfers full-body motion and facial expression onto your character in either animation or replacement mode.
by @AIOZAI